stefan (stefbun)

Posts
10776Following
97Followers
83I do stuff with taxes for a living and occasionally touch server-stuff for a hobby (when I am not banging my head against it and want to throw it out the window)
I love dressing girly occasionally, call me crossdresser. All future pics for that will be posted on my picdump-account on my sharkey-instance: https://shark.lightnovel-dungeon.de/@stefan (I will vet the followings there)
I also love sewing and reading (Light Novels especially)
stefan (stefbun)
stefan
Today Tagesschau has a shot for @aetios
Source: https://images.tagesschau.de/image/be5f79c4-47d1-4152-9b73-cdf08b0c41a4/AAABoTUkIAo/AAABnSStX0g/1x1-big/spacex-weltraumqualle-100.webp
The alt-text is german but you will manage
The gist is: It was taken after the launch SpaceX Falcon 9 Rocket for Transporting mission CRS-35 from Nasa into Space. It produces the typical "jellyfish"-cloud. Gases expand under lower pressure and get illuminated by the sun
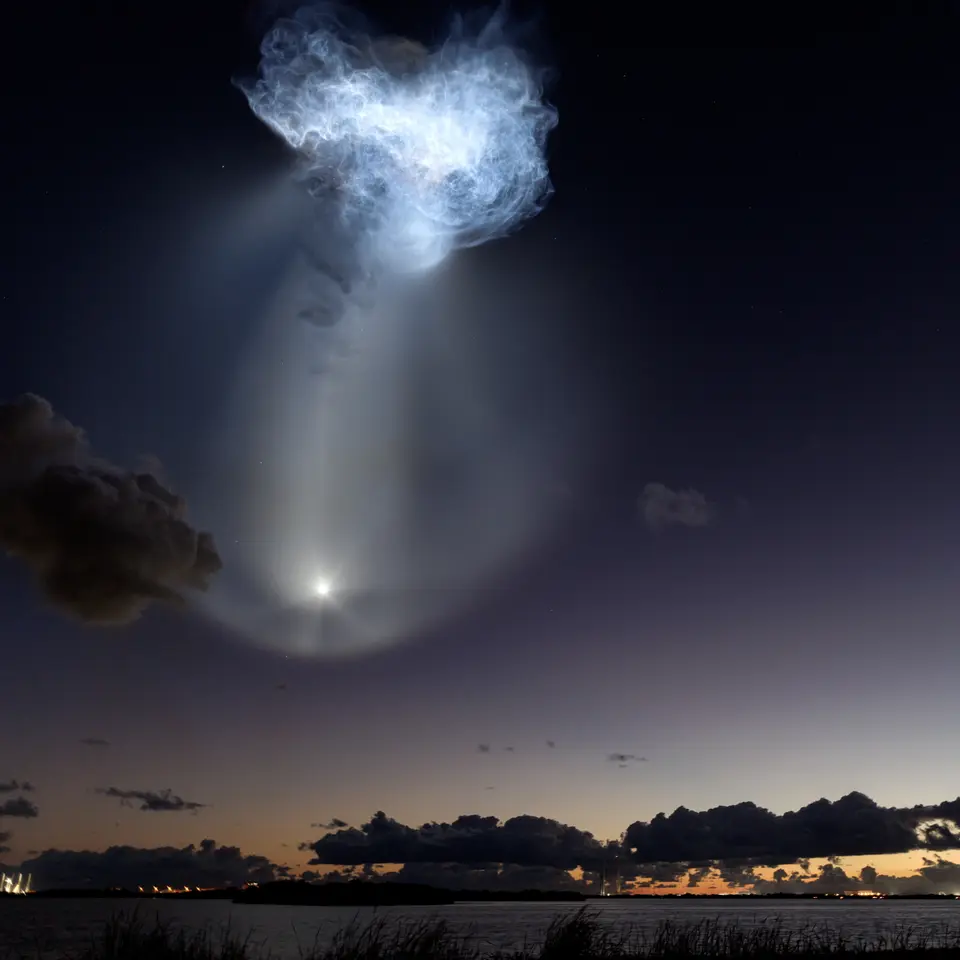
Source: https://images.tagesschau.de/image/be5f79c4-47d1-4152-9b73-cdf08b0c41a4/AAABoTUkIAo/AAABnSStX0g/1x1-big/spacex-weltraumqualle-100.webp
The alt-text is german but you will manage
The gist is: It was taken after the launch SpaceX Falcon 9 Rocket for Transporting mission CRS-35 from Nasa into Space. It produces the typical "jellyfish"-cloud. Gases expand under lower pressure and get illuminated by the sun
 0
 0
 0
stefan (stefbun)
stefan
Edited 9 hours ago
@feld @grillchen @kaia This is more a matter of consent. If someone puts up a thing on a blog on the internet you can usually safely assume they wanted to be seen by others. Otherwise they would have taken measures to prevent you from seeing it.
But yeah from a legal standpoint yeah it can be infringement. But rather on the basis that you actually make a copy of the website on your machine (caching and stuff. There is a long list of legal battles on that subject with video streaming lol)
Even assuming everyone is fine your crawler seeing things they might not be fine with any other uses.
The question really becomes is scraping the web to create a learnset for an LLM fair use or not? Where does fair use start end? Academic use? Commercial use?
Who actually owns the stuff an AI produces? What about the stuff there was no consent aquirred to be used as training data? What about AI routinely ignoring robots.txt and sneaking in through spoofing? Is that enough to claim unauthorized use?
But how can you claim that since the models are closed you cannot know what they ingested.
The copyright issues around are numerous and they do not stop at scraping
edit: Courts have also long since decided that snippets and indexing of search engines is fair use indeed. Ask google and its cases and the likes of Axel Springer. (They did lose with Google News)
1
0
0
stefan (stefbun)
stefan
@grillchen @kaia Just needed to leech off the whole internet without consent beforehand. Thats how to own the rich!
Wait nah you actually just made life shittier. It would have been the better approach to litigate the shit out of them. But the foundations with the pockets to do so are way to much slopping themselves right now.
AI made copyleft even more of a joke. But they allowed it to happen
I would not gone down the rabbit hole tbh.
0
0
1
stefan (stefbun)
stefan
@grillchen @feld @kaia I don't think people really trust adobe... its more of a forced relation. Capital and Time expenditure to learn something else (Davinci resolve exists...) is a fucking nightmare so keep paying for adobe.
the open source thingie might be cool or it might be utter dogshit. I am not a pro to know that. But don't would want to trust a project that is developed by one dude and his AI (as a company). Dude will have to stick around to maintain shit.
We all have seen how bad trusting in some thanklessly maintained software can end.
0
0
1
stefan (stefbun)
stefan
@grillchen @feld @kaia tbh AI was never on the side of open source tbh. Its just convinient for them.
The big AI firms are too occupied pumping a bubble. Adobe and a legal battle are not in their interest. I don't see them put any money into that. But maybe they do if the marketing sounds right.
Look at our shitty propability generator putting a juggernaut in the Creative space in danger.
The big AI firms are too occupied pumping a bubble. Adobe and a legal battle are not in their interest. I don't see them put any money into that. But maybe they do if the marketing sounds right.
Look at our shitty propability generator putting a juggernaut in the Creative space in danger.
1
0
0
stefan (stefbun)
stefan
@feld @grillchen @kaia Tbh I would not wanna run into the risk if there even being chance of stuff like this not be cleanroom.
You can never what the fuck is in it.
Well we will how this ends up and how the project will be supported in the end. I do not expect AI stuff to be super maintainable. But I might be wrong.
Will be interesting to see how this plays out for adobe. For now its just a neat plaything but nothing you should trust for work..
1
0
0
stefan (stefbun)
stefan
@feld @grillchen @kaia Good luck claiming "cleanroom" on anything that AI touched tbh. You cannot say for certain what the AI has and has not seen.
Might just throw money at the problem (lawyers) and silence the dev lol. But there are other problems that might get the project in hot water. Interface design etc.
Might just throw money at the problem (lawyers) and silence the dev lol. But there are other problems that might get the project in hot water. Interface design etc.
1
0
0


 )

stefan (stefbun)
stefan
@Johann150
You: My opsec is so good I don't get called
Me: I have phone numbers but never gave it to anyone and have not landline connected
We are not the same.
(I do get annoyed on mobile though)
You: My opsec is so good I don't get called
Me: I have phone numbers but never gave it to anyone and have not landline connected
We are not the same.
(I do get annoyed on mobile though)
0
0
0